Category: Programming

  • What metadata does malloc need?

    I read this article via Hacker News, where Senthilnathan explains why, if you want to allocate 13 bytes, it allocates more behind the scenes.

    He writes that what you end up with, after running malloc, is this:

    +----------------+
    |     Header     |
    +----------------+
    |    Variable    |
    |    padding     |
    +----------------+
    |  Back pointer  |
    +----------------+
    |  User memory   |  <- Pointer returned by malloc
    +----------------+

    But this, I have to point out, is his own implementation, which he shows in the article. Glibc uses a different implementation. I wrote a memory allocator back in 2014 which used yet a different layout.

    In short; Senthil creates a header (basically the size of request), a variable padding (which is not properly explained), and a back pointer that points back to the header.

    So when the memory is freed, free() can take the pointer (user memory), go one step back and use the back pointer to find the pointer to the original header that contains the size of the block, including the size of the padding, and free it properly.

    Regarding the variable padding, Senthil write: “it needs to hand back a pointer that’s correctly aligned for whatever type the caller is about to store there.” and “depending on what alignment was requested.”

    However, malloc doesn’t know the type that the caller is planning to store. It takes one argument, and that is the number of bytes requested. It does not ask for alignment.

    Luckily he links to the code in Github, and it seems he has made his own allocator that does take alignment as an argument, which means that this is not an implementation of malloc at all.

    My 2014 implementation of malloc

    I made a memory allocator back in 2014 as part of a course.

    The course went into topics such as CPU cache lines, memory allocation, and how to create payloads in machine code that could be used in buffer overflow attacks. Fun stuff.

    My memory structure looked like this:

    +----------------+
    |  sizeAndTags   |
    |   (header)     |
    +----------------+
    |      next      | <- Pointer returned by malloc
    +----------------+
    |      prev      |  next, prev and the boundary tag
    +----------------+    is only used once the memory
    |    space and   |          block is freed
    |     padding    |
    |       ...      |
    +----------------+
    |  boundary tag  |
    |   (footer)     |
    +----------------+

    struct BlockInfo {
      size_t sizeAndTags;
      struct BlockInfo* next;
      struct BlockInfo* prev;
    };

    So with a request for n bytes, if the request is less than MIN_BLOCK_SIZE (BlockInfo + footer), I allocate MIN_BLOCK_SIZE, otherwise I make sure to round the request up to correct ALIGNMENT.

    #define WORD_SIZE sizeof(void*)
    #define MIN_BLOCK_SIZE (sizeof(BlockInfo) + WORD_SIZE)
    #define ALIGNMENT 8

    By rounding up, I do not need the “variable padding” Senthil uses, nor the back pointer.

    The memory I give out is correctly aligned, always, and it is also big enough to contain the information needed once it is inserted into the free list.

    If you request 13 bytes, the allocator will hand out 16 bytes. But the caller doesn’t know this, all it knows is that it has a pointer to memory that is at least 13 bytes, as requested.

    Since I used 8 as ALIGNMENT, I am free to use the lower 3 bits of sizeAndTags for, well, tags. I used “TAG_USED” (this memory is in use) and “TAG_PRECENDING_USED” (the adjacent memory preceding this one is in use).

    There is also a macro, SIZE, to get the correct size by masking out the 3 lower bits of sizeAndTags.

    #define SIZE(x) ((x) & ~(ALIGNMENT - 1))

    The boundary tag — in use when on the free list — is the size of the block (same as sizeAndTags), so you can go backwards and find the start of the memory block.

    That’s why we have the TAG_PRECEDING_USED. If this is set to 0 on a block we are freeing, we can safely assume that the preceding block in memory has a valid boundary tag that we can use.

    This also means we have to update this tag if the memory adjacent is allocated from the free list.

    The boundary tag is used for coalescing. Merging two free adjacent memory blocks into one bigger memory block. Senthil explains this well in his article.

    I remember spending a lot of time with pen and paper visualizing the memory layout and the pointer arithmetic.

    When I worked on this, the structure of the memory block itself was not the interesting part. The exercise was to make an implementation that performed well. Both in speed and in memory utilization.

    When and how long to search the free list for best fit, when to split a memory block from the free list, and whether to use the head or tail end of said split.

    The course supplied test cases with various memory allocations. 9 tests in total. My results, that I submitted before the deadline, ended up like this:
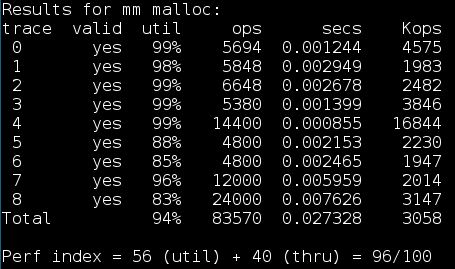
    Random, alternating big and small allocations, many small allocations, many free operations and back to big allocations to stress test coalescing and memory fragmentation.

    It turns out that memory fragmentation is a real thing, and you have to take care to minimize its impact.
  • Pay close attention to your network headers

    Summary: BIG-IP from F5 does not seem to honor the “Expect: 100-Continue” header by default, and changes must be made on the F5 appliance.


    Recently, an network application, which have worked since 2017, stopped working. The application is straigh forward enough. It checks if a service is working by doing (mainly) two things:

    1. Perform a “GET” using HTTP/1.1 to check for status 200
    2. Authenticate using Oauth 2.0 and receiving an access_token

    After a change was made to the endpoint, switching to BIG-IP from F5, the second step failed. Running the program in Visual Studio produced the following error message:

    The underlying connection was closed: An unexpected error occurred on a receive.

    Searching for this error message will provide you with a lot of various suggestions, mostly related to the TLS protocol.

    When I upgraded the project from .Net 4.8 to .Net 8.0, it started working. One difference I saw during the debugging was the headers sent by the application.

    Header sent using .Net 4.8:

    Content-Type: application/x-www-form-urlencoded
    Host: example.com
    Content-Length: 118
    Expect: 100-continue
    Connection: Keep-Alive

    Header sent using .Net 8.0:

    Content-Type: application/x-www-form-urlencoded
    Content-Length: 118

    A quick Google search on the phrase “Expect: 100-continue fails on F5” produced both an explanation and a fix. The short answer is that while the client is waiting for a “100 Continue” message, the F5 device is wating for more data.

    References:

    • https://my.f5.com/manage/s/article/K94382824
    • https://developer.mozilla.org/en-US/docs/Web/HTTP/Status/100
  • Knights of the Sky – Part 1

    Knights of the Sky – Part 1

    This post was written 4-5 years ago, back in October 2014, but for some reason never left the draft folder. Well, here it is. Maybe this will give me the necessary incentive to produce a part 2 in the near future.


    I’ve recently become interested in doing some small programming projects. Mainly using C and assembly language. For some reason low-level programming and embedded systems appeal to me.

    For fun, I decided to poke into the code of Knights of the Sky, the PC-version. A game which has given me hours of fun when I was young. Being a 16-bit DOS based game I thought it would be a relative easy task. The actual source code isn’t publicly available to my knowledge, so for this I had to look from the outside and in using different tools like hex editor and disassembly.

    How the game is assembled

    The game is split into several executables, none of which I was able to start directly from Dosbox. Neither was I able to disassemble them into anything useful. A quick peek using a hex editor reveals that they are compressed with the LZ91 algorithm. This isn’t a problem, the internet is full of tools which can uncompress them and make executables which can be dissassembled.

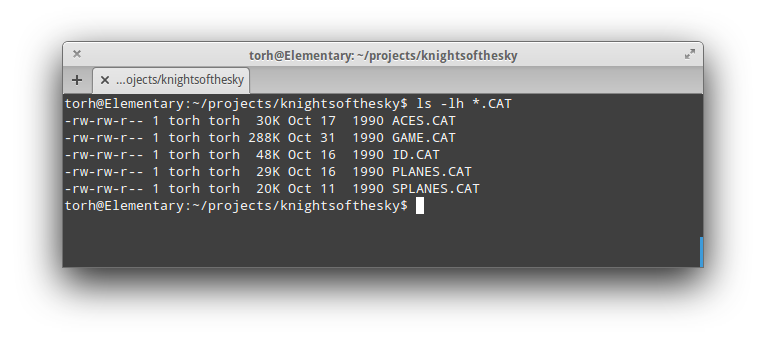
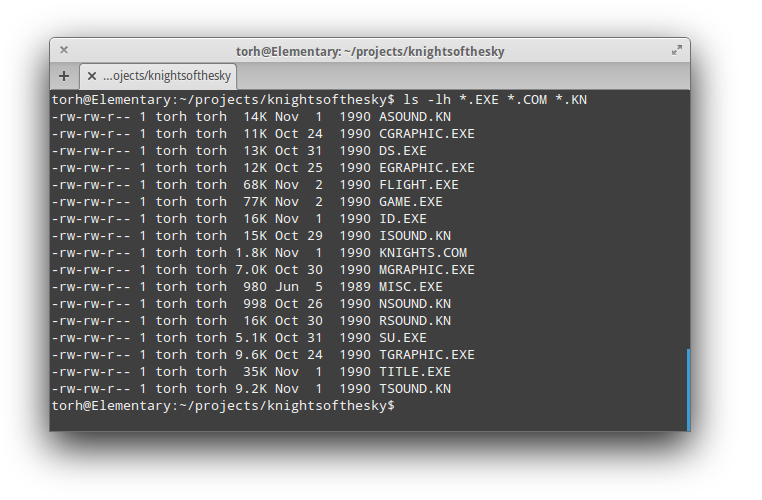
    Notice the timestamp of the files

    Splitting the files make some sense. Some because of the memory limit in early DOS era, but also because not all of the files are used. It all depends on the choices you make during setup, like sound and graphic options. Several of the executables have similar names, like CGRAPHIC.EXE, EGRAPHIC.EXE, MGRAPHIC.EXE and TGRAPHIC.EXE, and only one of them is used during game play. Same goes for sound.

    Playing Knight of the Sky

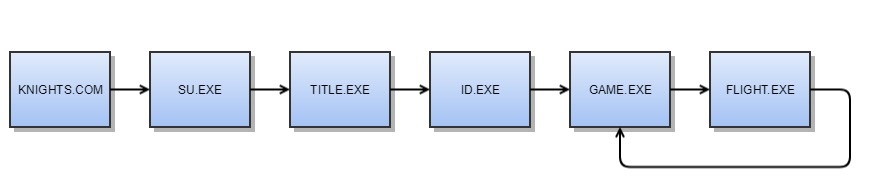
    To start the game the player would have to start KNIGHTS.COM, a basic binary executable which is loaded directly into memory location 0100h. This file acts as a loader which kicks off a chain of other executables.

    Knights of the Sky code execution
    My interpetation of the execution flow.

    SU.EXE is the setup where the player can choose input (keyboard, mouse and/or joystick), sound and graphics options. This is passed along to DS.EXE which, and I’m guessing now, is the part responsible for the stack and the memory layout (remembering the choices made, etc). After SU.EXE, DS.EXE is run between every executable until the player exits the game.

    Copy protection

    ID.EXE is the game “copy protection” scheme, where you are presented with an image and have to choose the right option. This is found in the game manual. Remember those?

    If the player selects wrong she or he is only able to play a training session. Again, I would guess that the result of this “copy protection” is also stored somewhere in memroy. MISC.EXE is also loaded into memory (overlay, not executed) by KNIGHTS.COM. This seems to be the code responsible for handling the game port (joustick). In my copy of the game this executable has a creation date of 1989, while the rest of the files are compiled in 1990.

    Catalog files – think of uncompressed .zip files – just a big buch of different data stored within the same file.

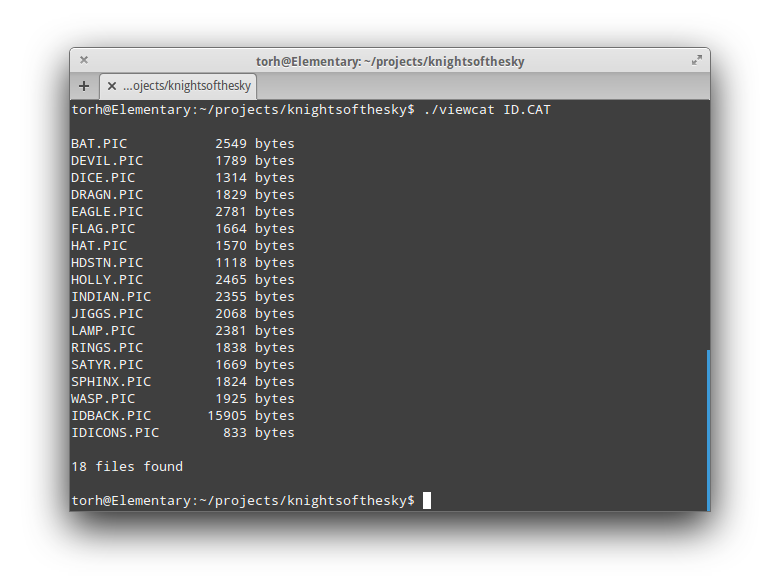
    Going back to ID.EXE, there is also a file called ID.CAT, which is basically a container for the images used by this executable. It contains one background image and several logos. One of the logos are presented and the user has to select the correct name which belongs to that particular logo. Creating a program to extract those files was (almost) straight forward after using a hex editor to figure out the internal data structure.

    The two first bytes tells how many files are “packed”, immediately followed by the following data structure times the number of the two first bytes. In this case, 18 times. The same structure is used for the other CAT-files in the game as well.

    struct fileHeader {
        char name[12];       // Filename with a maximum of 8.3, DOS-style
        unsigned short u1;   // ?? I Have no idea ??
        unsigned int size;   // File size in bytes
        unsigned int offset; // Offset from beginning of file
    }

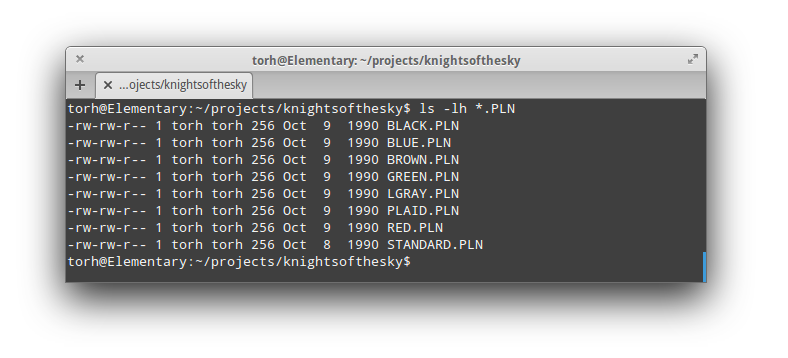
    There are also some files ending with PLN, all of which has the same size (256 bytes) and almost the same content. The name is almost a dead give away that we’re talking about different colors, and swapping one file with another reveals that these are responsible for the color of your plane, seen from the outside (hitting F2 during flight) that is. However they do not seem to impact the landscape in any way. I’ll just assume that PLN is an abbreviation of the word “plane”.

    Savegame file

    The last file I will mention is the ROSTER.DAT. This is the only file which changes during game play (did someone say save game?). It’s 35K bytes, and since the game supports 10 saved players (no more, no less), it was fairly easy to guess how much “space” each player occupies. The structure of this file has to be well-defined, but I have only scratched the surface so far. Then again, I’m more interested in decoding the graphics and sound then trying to cheat the game. It’s a pain to play without a joystick anyway.

    Now that we know where the different files are used and why, we are ready to dive deeper and do some real disassembly. The focus next will be on extracting and viewing images as well as be able to play the music from the game.

  • Disassemble DOS/4GW

    A few months ago I started tinkering with an old DOS-based game trying to figure out its internal data structure. Progress was good in the beginning, and I was quickly able to alter the saved game to give myself some advantages.

    Long story short, after a while I needed to figure out how the game handled a particular part of the savegame, since I couldn’t figure it out using a hex editor. But since the game was using a DOS extender, also known as DOS/4GW, loading it directly into Ida Pro Free wouldn’t help. It only gave meaningless garbage in return.

    The solution

    I found the open source DOS extender DOS/32. This has a utility known as SUNSYS Bind Utility which can be used to “Unbind and discard existing Extender/Stub from LE/LX/LC executable” as it says in the documentation.

    Place the utility, along with the executable in question, in the same directory and fire up Dosbox (or the real thing) and enter the following command.

    SB /U filename.exe

    This will produce a unbinded file which can be loaded directly into Ida Pro Free. In my case I ended up with a file ending in .LE, which stands for “Linear Executable”.

    Hopefully this can help others who want to peak into old DOS games.

  • Learning C

    Reading “The C Programming Language (2nd Edition)” by  by Brian Kernighan and Dennis Ritchie. Probably the best book I’ve read about programming so far. Straight to the point. And this from a book that was last revised in 1988.